I build the data infrastructure that recognises revenue at scale.
Microsoft Fabric · Azure · Power BI · Databricks · Spark · Python · SQL
Batch and streaming pipelines, governed reporting platforms and AI-driven analytics across banking, telecoms and government.
Ten years owning delivery end to end with client discovery and scoping, architecture and build, then the team that runs it.
Data engineering should change
what the business can do.
I build data systems around real business decisions — improving revenue, understanding customers, and making operations more efficient. The engineering matters, but the outcome is what counts.
Turn data into revenue
Sales forecasting, lead generation, marketing ROI and e-commerce analytics that help teams identify where revenue is coming from, where it is leaking, and where to invest next.
Make customer behaviour useful
Segmentation, behavioural analysis, loyalty and automated customer experiences that turn fragmented customer data into better targeting, retention and engagement.
Make the business run smarter
Financial processing, inventory, operational workflows and APIs that reduce manual work, improve visibility and give teams reliable data for faster decisions.
Selected work
Client names and system names are withheld under NDA. The architecture, the trade-offs and the results are not.
Telecoms · Streaming · Observability Streaming Delivery Observability
Event-driven telemetry platform for a high-volume messaging service used by retail banks. Idempotent webhook ingestion with schema validation at the boundary, micro-batched to object storage, status-reconciled in Spark and served with sub-ten-minute freshness. Gave operations the SLA evidence trail that provider credit claims had previously been argued without.
Streaming Delivery Observability
Event-driven telemetry platform for a high-volume messaging service used by retail banks. Idempotent webhook ingestion with schema validation at the boundary, micro-batched to object storage, status-reconciled in Spark and served with sub-ten-minute freshness. Gave operations the SLA evidence trail that provider credit claims had previously been argued without.
StackDockerised Spark · Azure Data Lake · Azure Blob Storage · SQL Server · Python scheduler · Power BI · webhook ingest with schema validation and IP allowlisting
- Context
- Delivery-status webhooks arriving continuously at high volume. Operations needed per-message status visibility within ten minutes to diagnose failures against provider SLAs.
- Options
- Managed message bus · managed event streaming service · containerised Spark with batched writes to object storage.
- Decision
- Containerised Spark, batching webhook payloads to object storage before processing.
- Why
- Write-cost per event dominated at projected volume; both managed options priced per message. Batching traded roughly two minutes of latency for a large reduction in storage transaction cost, comfortably inside the ten-minute requirement.
- Consequence
- Materially cheaper and simpler to operate, but the latency floor is now batch-interval-bound. Revisit if the requirement tightens below five minutes.
Business impactConverted an unmeasured operational risk into a contractual position, and made provider performance arguable with evidence.
Reported as generic. Client, platform and provider names withheld.
Read full case study →Finance · Governance · Access control Governed Financial Reporting Platform
Governed financial reporting platform replacing a manually assembled spreadsheet process with a single semantic model, controlled report catalogue and Finance-owned access governance. Directors receive self-service unit-level P&L while dynamic row-level security prevents unauthorised financial visibility. Access requests are submitted through an organisation-restricted Microsoft Forms workflow, validated by Python ETL and reconciled into an MDM-controlled access matrix. Finance owns the data source, reporting asset and access decisions; the platform automates their enforcement.
Governed Financial Reporting Platform
Governed financial reporting platform replacing a manually assembled spreadsheet process with a single semantic model, controlled report catalogue and Finance-owned access governance. Directors receive self-service unit-level P&L while dynamic row-level security prevents unauthorised financial visibility. Access requests are submitted through an organisation-restricted Microsoft Forms workflow, validated by Python ETL and reconciled into an MDM-controlled access matrix. Finance owns the data source, reporting asset and access decisions; the platform automates their enforcement.
StackSQL Server · automated ETL · Power BI semantic model · dynamic row-level security · Microsoft Forms with organisational restrictions · Python access-management ETL · Finance-owned MDM · report catalogue
- Context
- Financial reporting was being assembled manually from multiple disparate reports and queries, then captured into spreadsheets for verification and distribution. Month-end reporting could take hours to days and still lacked complete visibility, while manual distribution created a material risk of exposing one business unit's financial information to another. Directors needed self-service access to their own P&L, while Finance needed assurance that users could not see financial data outside their authorised scope. The reporting estate also needed a maintainable catalogue so users could discover the appropriate report by fiscal period without relying on administrator knowledge.
- Options
- Separate departmental reports and semantic models with manually managed access · a central report with application- or report-level filtering · a single governed semantic model with dynamic RLS, Finance-owned MDM and automated access provisioning, supported by a governed report catalogue.
- Decision
- Use a single governed semantic model with dynamic row-level security and multiple security roles. Maintain the user-to-organisational-scope matrix as Finance-owned MDM rather than embedding individual assignments in Power BI. Route access requests through organisation-restricted Microsoft Forms; Finance approves the request, and Python ETL validates the submission before updating the MDM access matrix. Power BI consumes the resulting security mapping to enforce access. Maintain a report catalogue indexed by fiscal period so users can discover governed reporting assets, while allowing the final Power BI report to supplement catalogue metadata with the required data and measures.
- Why
- Separate departmental models would multiply maintenance and create opportunities for financial definitions, calculations and security rules to drift between reports. A single semantic model provides one governed definition of financial measures while dynamic RLS enforces organisational boundaries at the data layer. Keeping access assignments in Finance-owned MDM separates the business decision of who should have access from the technical mechanism that enforces it. Microsoft Forms provides a controlled and traceable request entry point, while Python validates and propagates approved changes rather than relying on administrator memory. The same model supports department changes by updating the MDM assignment instead of modifying individual reports or security configurations.
- Consequence
- The platform requires a stricter change and governance process because model, security and organisational-hierarchy changes can affect financial visibility. Any semantic-model change requires security validation, and Finance remains responsible for maintaining the authoritative access assignments. In return, reporting definitions are centralised, access decisions are governed outside the report itself, provisioning becomes repeatable and traceable, and department changes can be propagated by changing the MDM matrix rather than manually reconfiguring reports. The organisation also gains a discoverable reporting catalogue instead of relying on emailed spreadsheets, report links or administrator knowledge.
Business impactReplaced hours-to-days of manually assembled financial reporting with self-service governed reporting. Directors can access unit-level P&L without a control exception, Finance retains ownership of data and access decisions, and dynamic RLS provides technical enforcement of the approved organisational access matrix.
Reported as generic. Client and system names withheld.
Read full case study →Finance · Reconciliation · Revenue assurance Revenue Leakage Detection
Revenue-assurance platform reconciling operational work, CRM and billing data where millions in monthly revenue were being left unbilled. Built during a Dynamics CRM to Salesforce migration with no dependable shared key, inconsistent technician coding and a fragmented billing/ERP process. Combined canonical master-data management, deterministic and fuzzy entity resolution, incremental Fabric ETL, Spark processing and Power BI diagnostic workflows, with human-in-the-loop review and governed overrides for ambiguous matches.
Revenue Leakage Detection
Revenue-assurance platform reconciling operational work, CRM and billing data where millions in monthly revenue were being left unbilled. Built during a Dynamics CRM to Salesforce migration with no dependable shared key, inconsistent technician coding and a fragmented billing/ERP process. Combined canonical master-data management, deterministic and fuzzy entity resolution, incremental Fabric ETL, Spark processing and Power BI diagnostic workflows, with human-in-the-loop review and governed overrides for ambiguous matches.
StackT-SQL · SQL Server · Microsoft Fabric ETL · Apache Spark · Power BI · master data management · deterministic and fuzzy entity resolution · incremental loading · caching · human-in-the-loop review
- Context
- Millions in revenue were being lost to unbillable work each month across disconnected operational, CRM and billing/ERP processes. Technicians recorded work using non-standard descriptions and codes, source systems used different identifiers and code sets, and the organisation was simultaneously migrating from Dynamics CRM to Salesforce. There was no reliable shared key for reconciliation, while billing processes were not sufficiently streamlined to expose delivered-but-uninvoiced work consistently.
- Options
- Single-system reporting from the CRM or ERP · full-refresh ETL with rule-based reconciliation · a central reconciliation and MDM layer using deterministic matching with fuzzy fallback and human-in-the-loop adjudication, processed incrementally through Fabric and Spark.
- Decision
- Build a canonical reconciliation and MDM layer across operational, CRM and billing/ERP data. Normalise source records and code sets, apply deterministic matching where identifiers were reliable, use fuzzy matching for unresolved entities, and route ambiguous cases to analysts through a HITL workflow. Persist approved analyst overrides as governed master-data inputs. Use incremental Fabric ETL and Spark for the complex reconciliation workloads, with SQL Server/T-SQL for relational transformations and Power BI for diagnostic and review dashboards.
- Why
- Accuracy was prioritised over raw processing speed because an incorrect match could either manufacture a leakage case or conceal genuinely billable work. A reconciliation layer also insulated revenue-assurance logic from the CRM migration and inconsistent source-system semantics. Incremental loading and caching avoided repeatedly processing stable historical data, while Spark provided a practical execution layer for the more complex reconciliation workloads. HITL review ensured low-confidence matches were adjudicated rather than silently accepted, and the MDM layer made those decisions reusable and governed.
- Consequence
- The solution introduced more architectural complexity and an ongoing data-stewardship requirement, but converted fragmented and unreliable source data into an auditable revenue-assurance process. High-confidence records could be reconciled automatically while ambiguous records were surfaced with diagnostics and supporting evidence for analyst review. Approved overrides became reusable master data rather than one-off dashboard decisions. The architecture also remained usable through the Dynamics-to-Salesforce migration because reconciliation was based on a governed canonical layer rather than dependence on a single CRM's identifiers or coding conventions.
Business impactCreated a repeatable revenue-assurance capability that exposed millions in monthly unbillables, replacing manual investigation with governed reconciliation, diagnostic evidence and human-reviewed exceptions. Figures available on request.
Reported as generic. Client, system and platform-specific business details withheld.
Read full case study →Platform · Reliability · Cost Platform Reliability Monitoring
Observability layer for the reporting estate. Gateway health, dataset refresh outcomes and agent job state ingested into a modelled serving layer, with alerting bound to SLO breach rather than raw failure count. Paired with a capacity scheduler that parks idle compute, so reliability and unit cost improved on the same change.
Platform Reliability Monitoring
Observability layer for the reporting estate. Gateway health, dataset refresh outcomes and agent job state ingested into a modelled serving layer, with alerting bound to SLO breach rather than raw failure count. Paired with a capacity scheduler that parks idle compute, so reliability and unit cost improved on the same change.
StackPower BI Gateway telemetry · SQL Server Agent · Python ETL · custom capacity scheduler pausing idle compute
- Context
- Refresh failures were discovered by users, not engineers. Separately, development database spend was growing without clear attribution to teams.
- Options
- Vendor monitoring add-on · manual audit cadence · build telemetry ingestion and a capacity scheduler in-house.
- Decision
- In-house telemetry pipeline plus a scheduler that pauses capacity when idle.
- Why
- Availability ranked above cost, but the vendor option priced per-workspace and would have grown with the estate. Building it kept monitoring coverage complete while the scheduler paid for the effort within months.
- Consequence
- Failures fell sharply and spend dropped roughly a third, but the telemetry pipeline is now itself a system requiring maintenance and its own monitoring.
Business impactFailures found by engineers instead of executives, and a material reduction in platform run-rate on the same piece of work.
Reported as generic. Client and platform names withheld.
Read full case study →The Engineer Behind the Outcomes
A Senior Data Engineer who connects technology to the decisions and outcomes that matter. Explore the work first, then get to know the engineer, experience and capabilities behind it.
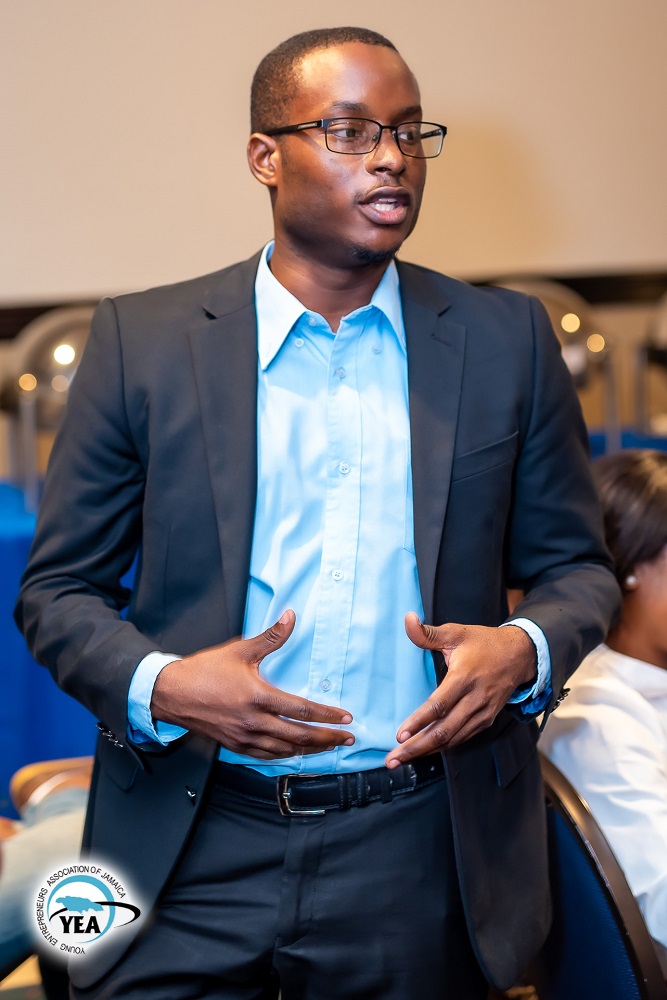
Gilroy Gordon is a Data & AI leader, analytics engineer and educator with over ten years delivering measurable impact across private sector, government and nonprofit organisations internationally. He specialises in building scalable data platforms, AI-driven solutions and intelligent automation that improve revenue performance, customer experience and operational efficiency.
A multi-certified Data & Analytics professional, including Microsoft, and a Certified Scrum Master, he combines deep technical expertise with strategic leadership to help organisations translate data into competitive advantage. Gilroy has chaired AI and Data committees, developed Data and AI academic programmes at the University of Technology, Jamaica, and presented at regional and international forums including IEEE workshops and BizTech.
He remains committed to community service, mentorship and capacity building, and has been active in service organisations supporting initiatives that strengthen digital and social impact ecosystems. He is humbled to have been recognised in the Nova Scotia Legislature for contributions to Legal Aid initiatives affecting over 400,000 Canadians, to have been named Young Entrepreneur of the Year in 2020, and to keep finding opportunities in youth development.
The full record
Career history, certifications, education, publications, awards and recommendations are maintained on LinkedIn rather than duplicated here.
Learn more on LinkedIn →Case Studies
Read about the work, the decisions behind it, and what it delivered.
View Case Studies →What I work across
Layered the way a platform actually is, rather than as an inventory.
Everything else in the toolkit — languages, servers, platforms, methods
Languages
SQL · T-SQL · HiveQL · Python · C# · ASP.NET · Java · JavaScript · TypeScript · PHP · R · C · C++ · Dart (Flutter) · Solidity · Cypher · Pig Latin · Bash · HTML5 · CSS
Data & big data
Microsoft Fabric · Azure Data Factory · Azure Databricks · Azure Data Lake · OneLake · Apache Spark · Hadoop · Hive · HBase · Sqoop · Apache Pig · Impala · Zeppelin · Ambari · Kafka · Airflow · dbt · SSIS · Snowflake · KNIME
Databases
SQL Server · MySQL · PostgreSQL · SQLite · MongoDB · Neo4J · Lucene · Solr
BI & reporting
Power BI (Embedded · RLS · Gateway administration · DAX tuning) · SSAS · SSRS · Tableau · Looker Studio · SAP Crystal Reports · Jupyter · R Studio · Excel & Power Query
AI, ML & automation
MLflow · Hugging Face · LLMOps · NLP · Generative AI · recommendation systems · predictive modelling · RPA · Power Automate · web mining
Ship & run
Azure DevOps · Git · GitHub · GitLab · Bitbucket · Team Foundation Server · Subversion · Travis · Docker · Kubernetes · Ansible · Linux · Windows · Android · ARMv6
Application & servers
Node.js · React · Angular · Laravel · Bootstrap · IIS · Apache · NGINX · Tomcat · IBM WebSphere · Glassfish · WordPress · Joomla · Magento
Delivery
Agile · Scrum (Certified ScrumMaster) · Kanban · Waterfall · RAD · Lean Six Sigma (White Belt) · Project Management Essentials
Working on something that needs to be trusted?
Two doors, depending on what you need.
Talk to me directly
Full professional history, current work and experience live on LinkedIn. Best route for permanent, contract and lead engineering roles.
Bring in the team
IGonics is my consultancy. Data platforms and warehousing, analytics and BI, AI and automation, systems integration and custom software — scoped, delivered and supported by a team rather than one pair of hands.